The phrase “From Verizon Disaster to Long-Term Support Client” sounds dramatic—until you live it.
This case-style guide walks through how a single ISP meltdown turned into a structured, repeatable response: stabilize operations, document what happened, hold vendors accountable, and convert chaos into a sustainable support model. If you’ve ever searched from verizon disaster to long-term support client at 2 a.m. while your business is offline, this is for you.

The “Verizon Disaster”: What Actually Happened
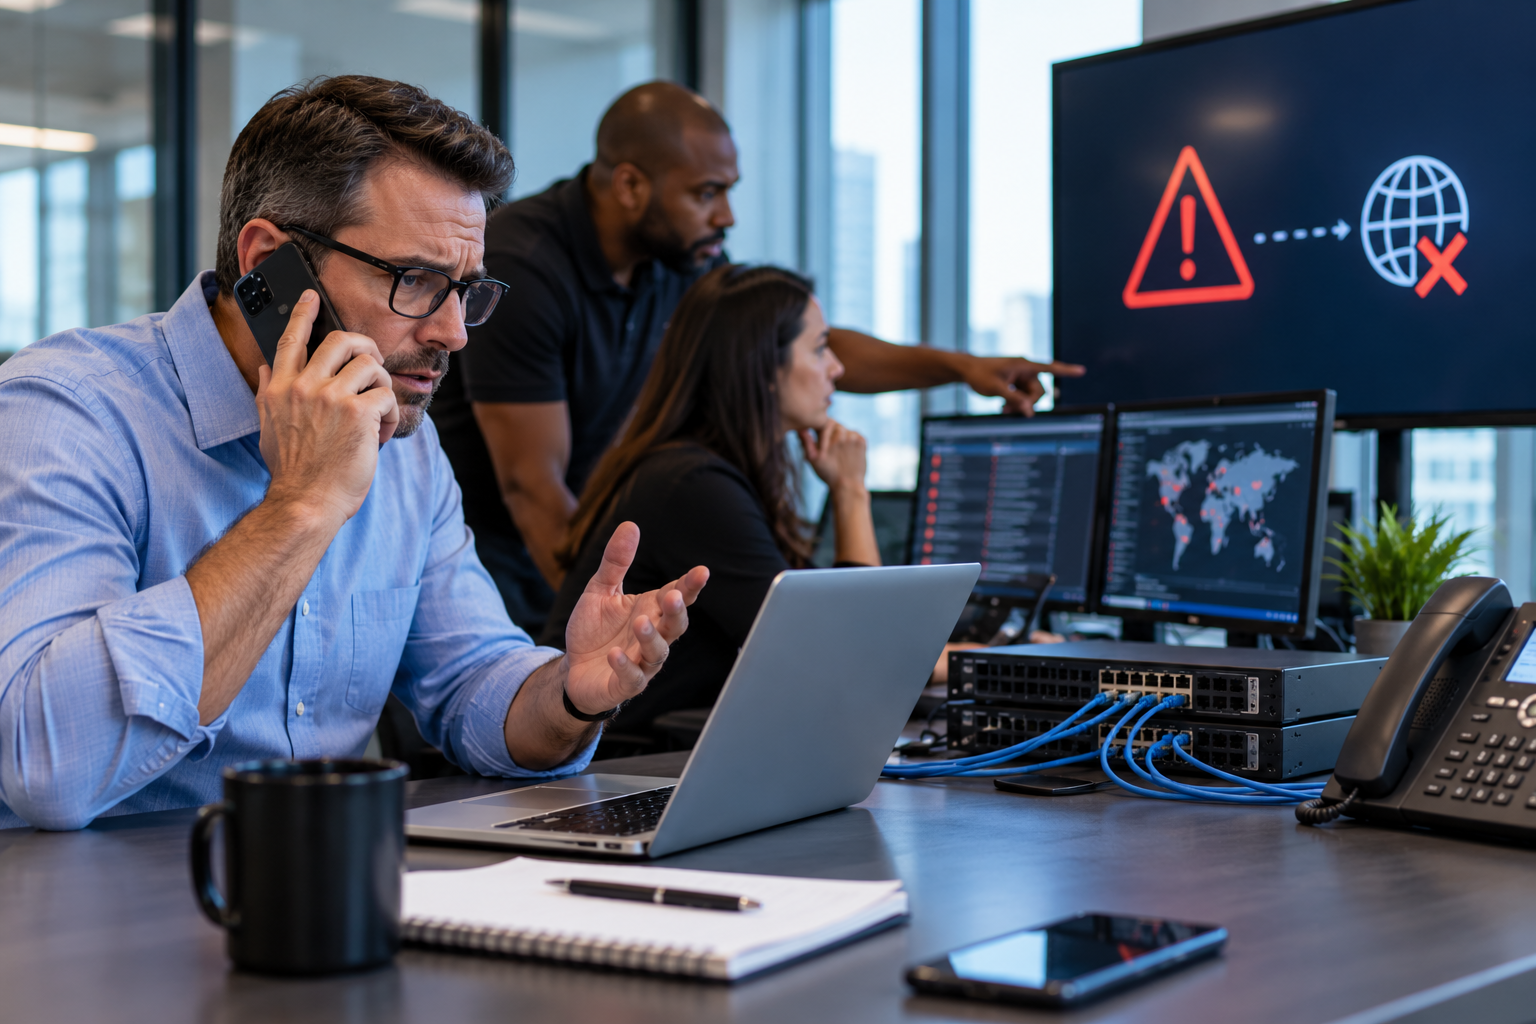
In this scenario, a mid-sized business running cloud apps, VoIP, and VPNs experienced a sudden carrier outage that looked like “the internet is down”—but quickly became a multi-system failure.
Typical symptoms we saw:
- Total loss of primary circuit connectivity
- VoIP instability and dropped calls
- Remote employees unable to authenticate via VPN
- POS and SaaS apps timing out
- Leadership asking, “Is this us or Verizon?”
This is where telecom service failure mitigation matters: you can’t fix the carrier’s network, but you can reduce blast radius and time-to-recovery.

First 60 Minutes: The Verizon Outage Recovery Plan (That Most Businesses Don’t Have)
A real Verizon outage recovery plan focuses on actions that work even when you don’t yet know root cause.
Immediate triage checklist
- Confirm scope: single site vs multi-site vs remote users
- Validate local network health: firewall, switches, power, handoff link
- Fail over if available: secondary ISP, LTE/5G, SD-WAN policy
- Freeze risky changes: no random reboots without logging
- Start a timeline: who noticed, what broke, what was tried
Tactical goal: reduce downtime after ISP outage by avoiding “thrash”—untracked troubleshooting that wastes time and destroys evidence.

Escalation Done Right: Verizon Business Support Escalation Without the Runaround
Most outages get prolonged because escalation is unstructured. Effective Verizon business support escalation looks like this:
- Open a ticket with business support (not consumer channels)
- Request an incident number, ETR, and outage confirmation
- Provide circuit ID, handoff details, and last-known-good time
- Ask for upstream status: last-mile, aggregation, regional event
- Get a named point of contact or escalation queue
This is also where SLA management and vendor accountability begins. If the provider can’t provide status, you document that gap—politely, precisely, and consistently.

Root Cause Analysis for Network Outage: What You Can Prove (and What You Can’t)
After service is restored, leadership wants answers. A strong root cause analysis for network outage doesn’t guess—it separates facts from assumptions.
What you can usually determine:
- Whether the LAN was healthy during the event
- Whether the edge firewall saw carrier handoff drop
- Whether failover succeeded or failed—and why
- How long each department was impacted
What you often can’t fully prove without the carrier:
- The exact upstream device or fiber segment that failed
- Whether a misconfiguration occurred within the ISP core
This is why incident postmortem template guide documentation matters.
A simple incident postmortem template guide (copy/paste)
Use this structure for every outage:
- Summary: what happened in one paragraph
- Impact: users, sites, systems, revenue exposure
- Timeline: minute-by-minute key events
- Root cause: confirmed + suspected, clearly labeled
- What worked: failover, monitoring alerts, comms
- What didn’t: escalation delays, single points of failure
- Action items: owner + due date + measurable outcome

Disaster Recovery vs Business Continuity: Why This Wasn’t “Just DR”
Many teams confuse disaster recovery vs business continuity:
- Disaster Recovery (DR): restoring IT systems after failure
- Business Continuity (BC): keeping the business running during the failure
ISP incidents are a BC problem first. The fastest wins usually come from:
- Dual WAN with automatic failover
- Cloud-managed DNS and identity resilience
- VoIP routing options (call forwarding, softphones)
- Clear internal comms plan (Teams/SMS/status page)
Verizon vs AT&T Business Internet (and Other Options): How to Evaluate
After an outage, leaders ask: “Should we switch?” The Verizon vs AT&T business internet decision should be evidence-based:
Compare:
- SLA terms and real escalation responsiveness
- Local last-mile diversity (same conduit = same risk)
- Mean time to repair history (ask for reports if possible)
- Cost of downtime vs cost of redundancy
Sometimes the “best Verizon alternative provider” isn’t AT&T—it might be a local fiber carrier, fixed wireless, or a different last-mile topology entirely. The goal is path diversity, not brand loyalty.
How to Switch ISP Smoothly (Without Creating a Second Disaster)
If you decide to move, how to switch ISP smoothly comes down to overlap and testing.
Practical migration steps:
- Keep old and new circuits live in parallel for 30–60 days
- Run load tests and VoIP quality checks
- Validate public IP changes, VPN tunnels, and firewall rules
- Update DNS carefully; reduce TTL ahead of cutover
- Schedule cutover during lowest-risk business window
- Document rollback steps and decision triggers
This is also a great time to implement managed network monitoring and alerting so your team hears about packet loss before your customers do.
The Turning Point: MSP Onboarding After Incident
The business didn’t just need “someone to call.” They needed a system.
That’s where MSP onboarding after incident becomes powerful: you capture the outage lessons and bake them into monitoring, redundancy, vendor processes, and documentation.
A good onboarding includes:
- Network discovery and diagramming
- Monitoring thresholds (latency, jitter, packet loss, circuit down)
- Escalation runbooks (including provider contacts and circuit IDs)
- Backup connectivity design recommendations
- Quarterly continuity testing
Why They Stayed: IT Support Retainer Benefits
Once the fire is out, many businesses go back to “break-fix.” This client didn’t—because they saw the IT support retainer benefits firsthand:
- Faster response with known environment context
- Proactive maintenance and lifecycle planning
- Better vendor management and escalation muscle
- Regular reporting that turns IT into measurable risk control
To formalize it, we used a long-term IT support contract checklist.
Long-term IT support contract checklist (essentials)
- Defined response times and coverage hours
- Monitoring scope (sites, firewalls, switches, Wi-Fi, circuits)
- Clear escalation paths and vendor-handling responsibilities
- SLA reporting cadence and outage postmortems included
- Quarterly DR/BC review and failover testing
- Documentation ownership and offboarding terms
Takeaway: Turn One Bad Outage Into a Better Operating Model
From Verizon Disaster to Long-Term Support Client isn’t about blaming a carrier—it’s about building resilience. Whether you keep Verizon, compare options like Verizon vs AT&T business internet, or pursue the best Verizon alternative provider, the winning move is the same: design for failure, document relentlessly, and enforce SLA management and vendor accountability.
If you do that, the next outage won’t be a disaster—it’ll be an incident with a plan.